Podcast RAG and Fine-Tuning
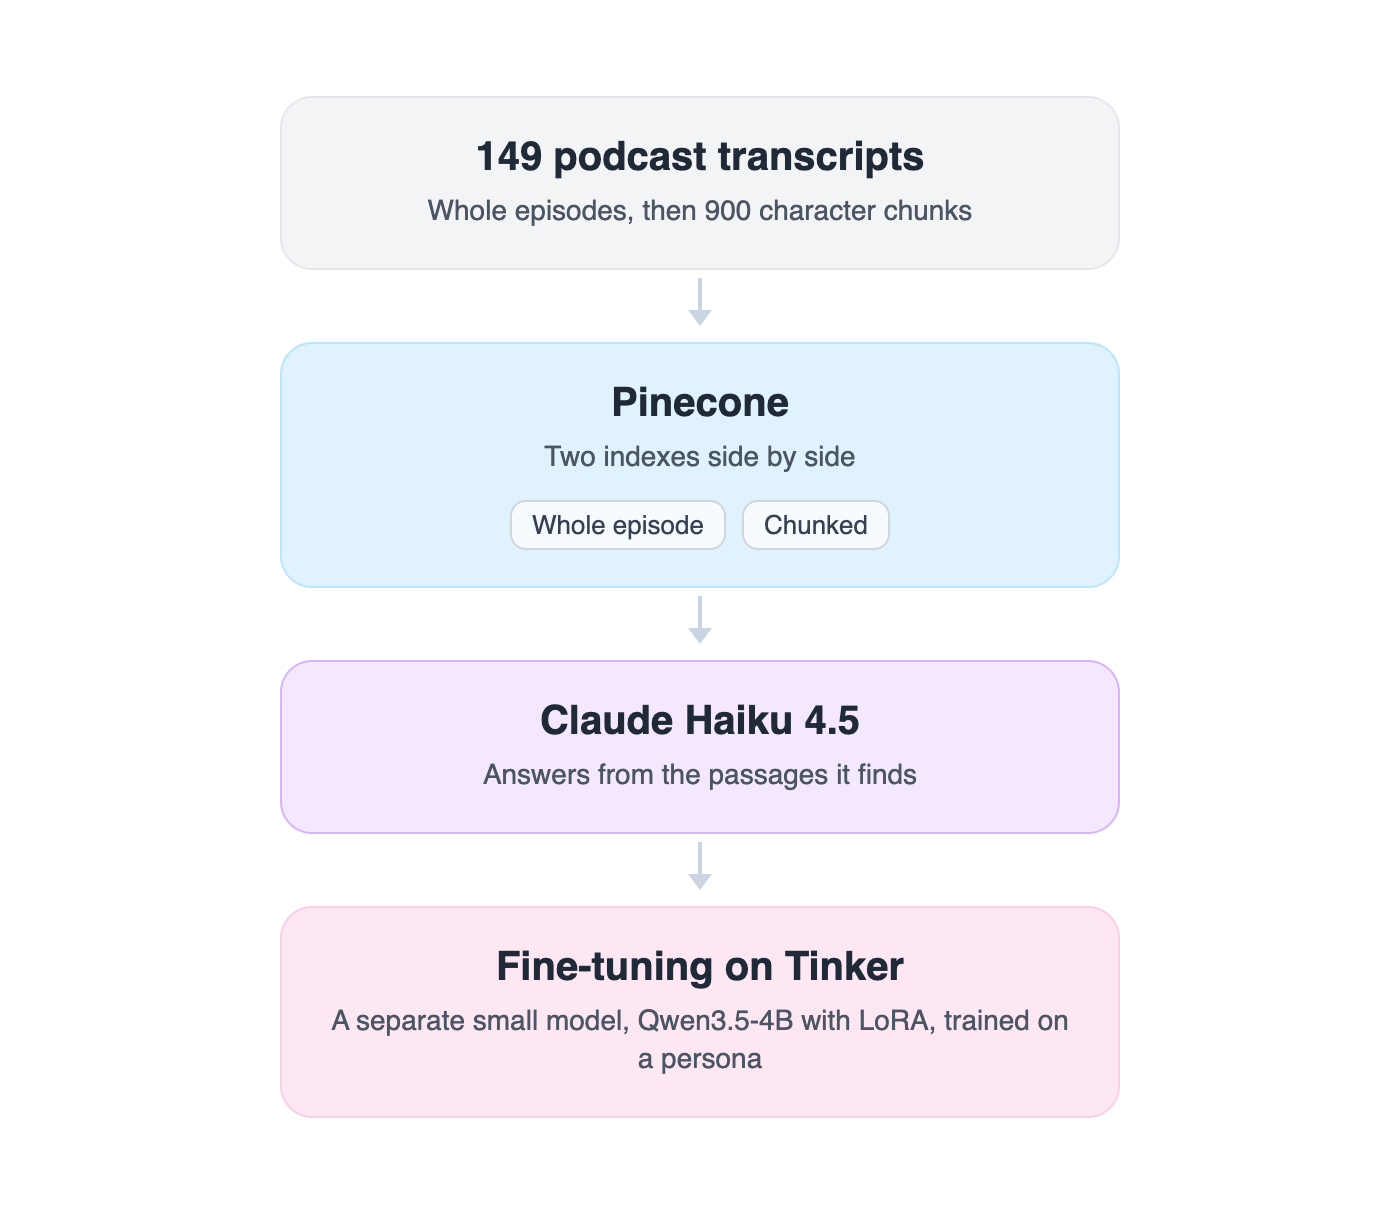
I built retrieval augmented generation from the ground up over 149 podcast transcripts. First I stored one vector per whole episode in Pinecone and let Claude Haiku 4.5 answer from what it found. It found the right topic but answered poorly, because a whole episode is too big to point at the passage that matters.
Then I split every episode into 900 character chunks with some overlap and loaded them into a second index. The app shows both side by side, so the same question can be asked of whole episodes and of chunks. Seeing the two answers next to each other made the case for chunking better than any explanation could.
The second half was fine-tuning. I picked a persona, trained Qwen3.5-4B with LoRA on Tinker for 54 steps, and watched the loss fall as it learned. Then I compared the plain model with the tuned one on the same prompts and chatted with my tuned model in the Tinker Playground.
The useful lesson was knowing which tool fits which job: retrieval for facts the model has never seen, fine-tuning for how it speaks.
Medha skipped presentations and built real AI products.
Medha Bansal was part of the August 2026 cohort at Curious PM, alongside 24 other talented participants.